Model Serving

Model serving encompasses the operational systems and infrastructure used to deliver artificial intelligence inference requests in production environments. Truncated covers inference hardware, serving frameworks, optimization techniques and deployment architectures.

Yesterday · Tue 10 Nov

Monday 9 November

Saturday 7 November

Friday 6 November

Thursday 5 November

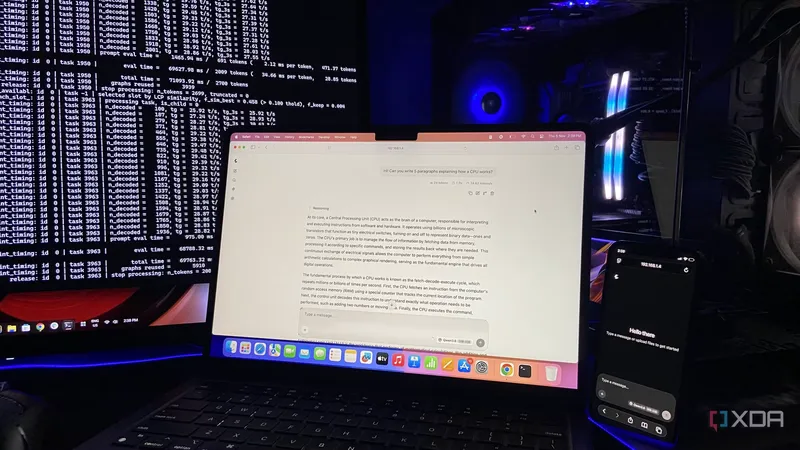
My gaming GPU sat idle most of the day, so I turned it into a local AI server the whole house can use

AI-generated summary An idle gaming graphics card can be turned into a home network server using software tools like llama.cpp to share local artificial intelligence capabilities across multiple household devices. By configuring specific parameters for hardware such as an RTX 4070 Ti Super, users can run models like Qwen3.6-35B-A3B locally while managing memory constraints between system RAM and video memory.