

FreeToken runs massive MoE models on consumer GPUs · IFAI
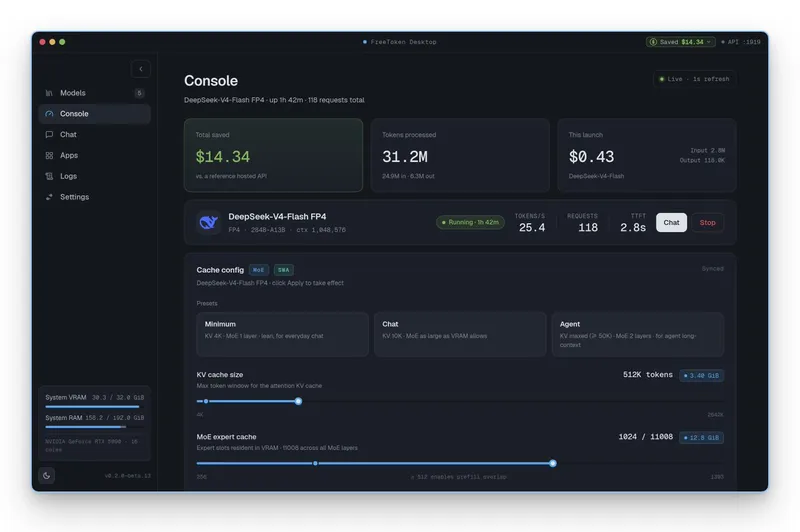
AI-generated summary Researchers from UC Berkeley and MIT have released an open-source inference engine named FreeToken that enables consumer personal computers to run large mixture-of-experts models. Using an RTX 5090 paired with 192GB RAM, the system achieves a decoding throughput of 22 to 25 tokens per second on DeepSeek 284B.