

Anemone: LLM Inference on the Apple Neural Engine, With a GPU Drafter, Exact Output and Half the Energy
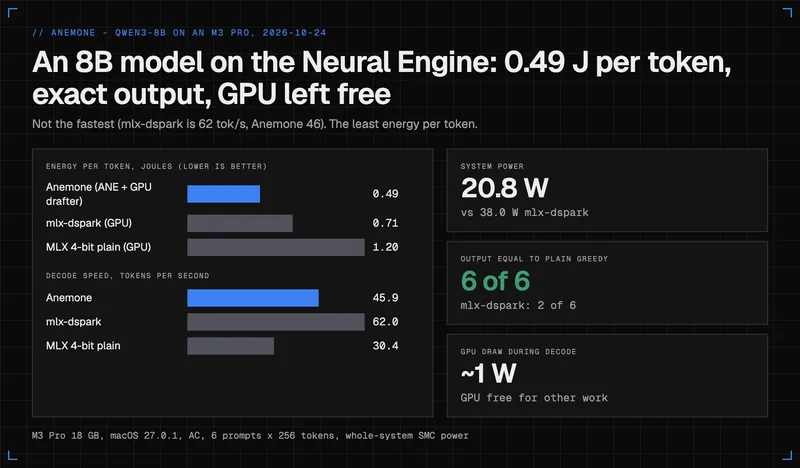
AI-generated summary Anemone is an open-source Swift engine that runs a large language model on the Apple Neural Engine alongside a small drafter on the GPU. On an M3 Pro, Qwen3-8B generates forty-six tokens per second at 0.49 joules per token, consuming less energy than plain MLX.