techwavedispatch.com · Mon 16 Nov

Monday 16 November

‘A complete evaporation of confidence’ – 6 things have to go right for Nvidia post Jensen, starting with $109 billion in revenue
AI-generated summary Nvidia reported that S&P’s Visible Alpha consensus expects third-quarter revenue of $109.3 billion following the departure of Jensen Huang. Colette Kress is serving as interim chief while the board considers candidates to replace Huang.

Also covered byPavitramsAxiostechwavedispatch.com
Earlier:

From Local Prediction Error to Final Outputs: A Theory of Expert Sharing in Multi-Step Reasoning

From Local Prediction Error to Final Outputs: A Theory of Expert Sharing in Multi-Step Reasoning

AI-generated summary Researchers analyze mixture-of-experts models that share experts across layers or computational steps to study how local prediction error reduction affects final outputs. The study examines linear regression models and trained Transformers to determine when sharing improves local estimation and when those gains survive to the final output.

Hyperparameter Search with Transformers and Ray Tune

alt_text

AI-generated summary In the Transformers 3.1 release, Hugging Face and Ray Tune integrated to offer a hyperparameter tuning solution for machine learning models. Users can access algorithms such as HyperBand, Bayesian Optimization, and Population-Based Training while fine-tuning models like BERT.

Earlier:

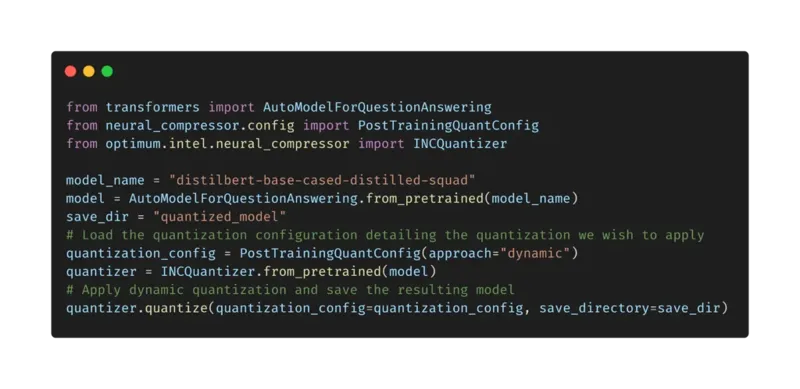
The Optimization Toolkit for Transformers at Scale

Automatic quantization code snippet

AI-generated summary Hugging Face reports that companies such as Tesla, Google, Microsoft and Facebook run billions of Transformer model predictions every day. Hugging Face says its new open source library named Optimum is designed to provide performance optimization tools targeting efficient AI hardware.

Earlier:

GPT-Neo and the 🤗 Accelerated Inference API

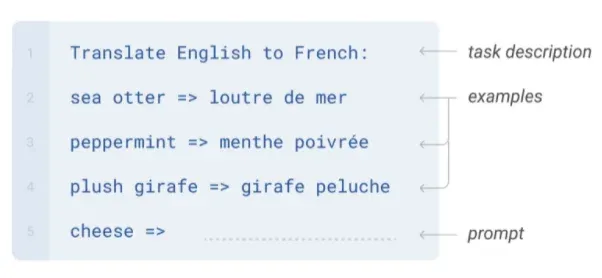
few-shot-prompt

AI-generated summary The blog post explores how GPT-Neo and the Accelerated Inference API can be used to generate predictions using Few-Shot Learning in natural language processing. GPT-Neo is a family of transformer-based language models from EleutherAI based on the GPT architecture, while the Accelerated Inference API is a hosted service to run inference.

Earlier: