Model Comparisons

Model comparisons evaluate the performance, capabilities and efficiency of artificial intelligence systems across various benchmarks and tasks. Truncated covers benchmark results, technical evaluations, methodology disputes and capability analyses between named systems.

Thursday 5 November

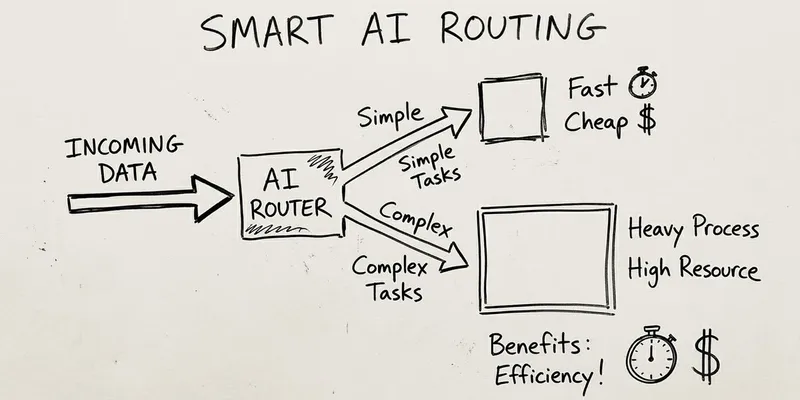
A $100 budget buys 40 Intelligence Index tasks (a mix of task archetypes) with Opus 5.5 at medium reasoning effort, or…

AI-generated summary A one hundred dollar budget purchases forty Intelligence Index tasks using Opus 5.5 at medium reasoning effort or ten tasks at maximum effort. The same amount covers one hundred sixty six tasks with DeepSeek V4.1 Flash 1017 at maximum effort or two thousand five hundred tasks with GPT-6 Luna at medium effort.

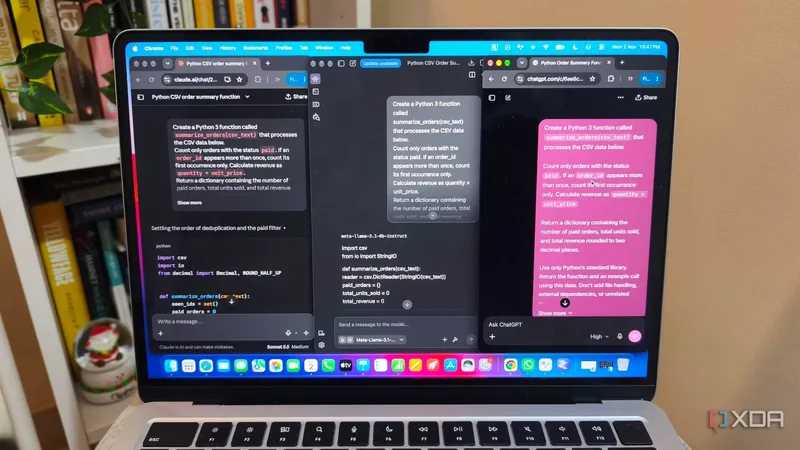
I gave Claude, ChatGPT, and a local 9B model the same 20 tasks, and only one was worth paying for

AI-generated summary An author evaluated Claude, ChatGPT, and a local 9B model on twenty everyday coding and troubleshooting tasks to determine whether subscriptions are worthwhile. The author finds that Claude provides the most usable assistance for complicated projects and justifies its subscription cost despite its usage limits.

Tuesday 3 November

Monday 2 November

Friday 30 October