Model Comparisons

Model comparisons evaluate the performance, capabilities and efficiency of artificial intelligence systems across various benchmarks and tasks. Truncated covers benchmark results, technical evaluations, methodology disputes and capability analyses between named systems.

Today · Thu 12 Nov

In the competition for cultural influence, AI has a default country

AI-generated summary Researchers at the University of the Basque Country and Cardiff University tested eight AI models across 24 languages with 31,680 variations involving open-ended questions about family life, culture, and tradition. The study found that six of the eight AI models consistently selected Japan as their default answer when filling in the blanks without any provided preferences or alternatives.

Yesterday · Wed 11 Nov

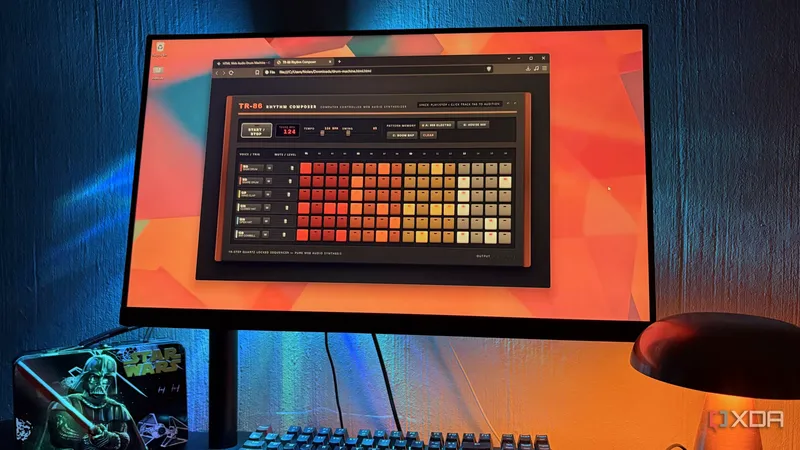
I made Gemini 4 Argon, Fable 5.1, and GPT-6 Astra build the same audio tool, and the best-looking one wasn't the best-sounding one

AI-generated summary Gemini 4 Argon, Fable 5.1, and GPT-6 Astra were tested on writing code for a drum machine audio tool using the Web Audio API. The models generated different visual designs and synthesized audio results, ranging from wood-panel aesthetics to distinct low-end sound output.

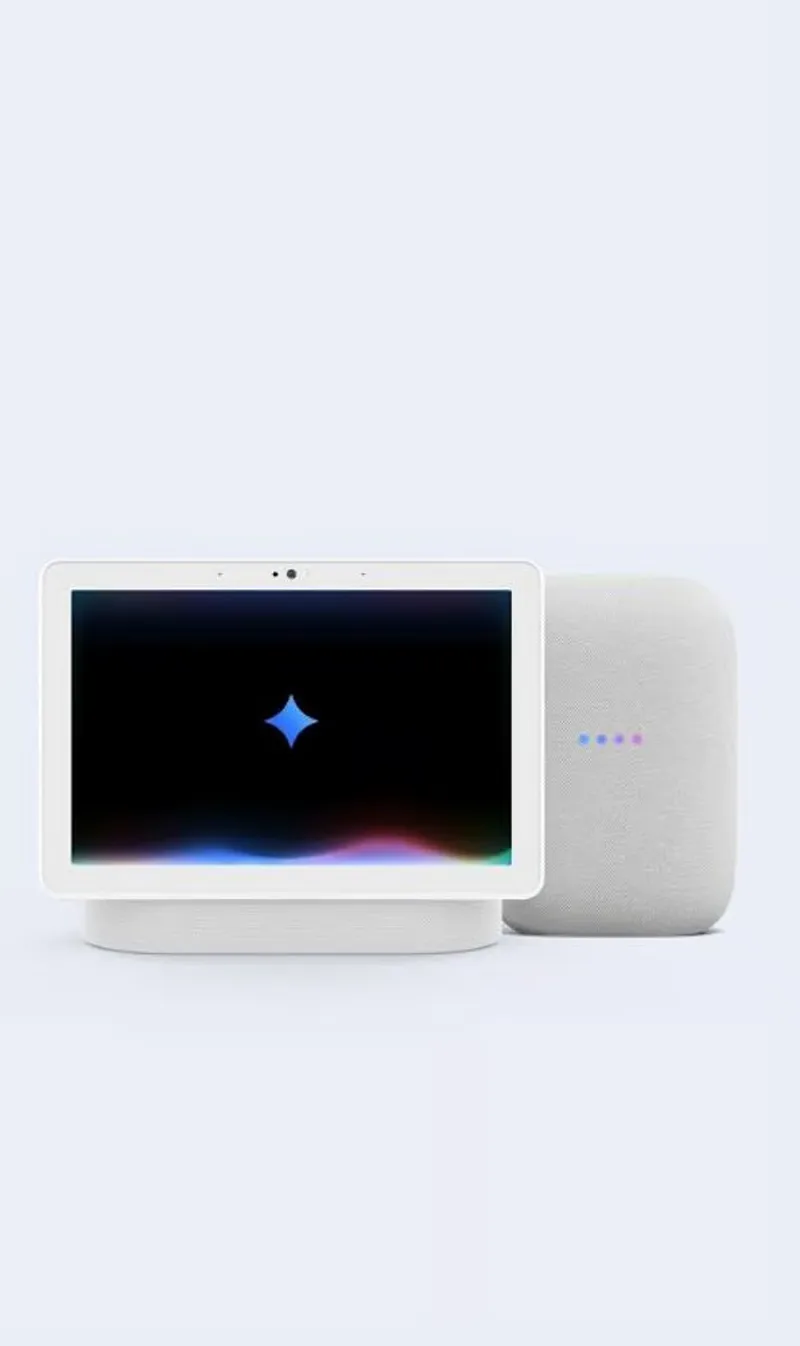
Google Gemini Vs Alexa Plus: Which Home Assistant is Better?

Google Gemini Vs Alexa Plus: Which Home Assistant is Better?

AI-generated summary Google Gemini is an artificial intelligence assistant that helps users control smart home devices, answer questions, and manage everyday tasks through compatible devices. Alexa Plus is a generative artificial intelligence assistant from Amazon that supports smart home controls, online shopping, and reminders through compatible Echo devices.

Tuesday 10 November

Monday 9 November

Five AI models tackled 227 pharmacy exam questions. Here's where they struggled

AI-generated summary Researchers at the University of the Pacific School of Pharmacy published a study in Scientific Reports comparing the accuracy of five large language models on 227 infectious disease examination questions. ChatGPT-4o-mini achieved the highest accuracy at 91.2 percent, while the evaluation showed that model performance declined on questions containing images.

Saturday 7 November

Friday 6 November

I gave Gemini 4 Argon in Antigravity and Claude Code the same messy side project, and only one of them left it better than it found it

AI-generated summary Google launched Gemini 4 Argon in Antigravity, which was tested alongside Claude Code on a port of a kindle-smarthome-dashboard for a 2015 Amazon Kindle Paperwhite. Claude Code wrote 63 tests and preserved the original visual layout, whereas Gemini 4 Argon made unrequested style changes that altered how cards appeared on the e-ink screen.

Thursday 5 November