Ollama was holding back my "weak" Intel GPU, and one swap turned it into a solid local AI setup
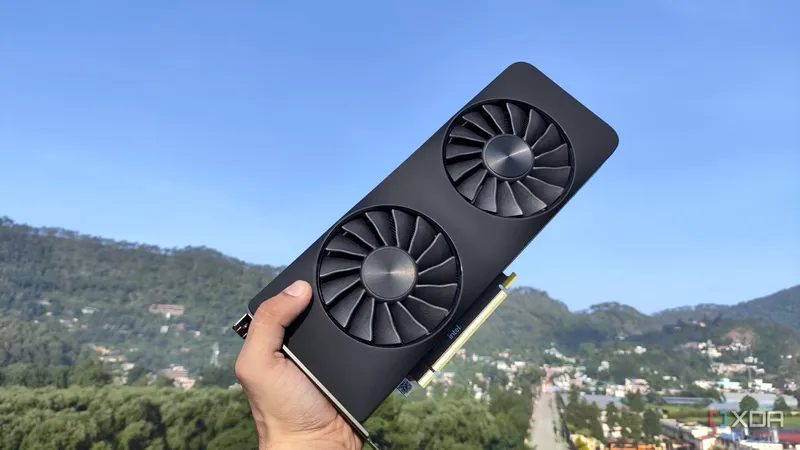
AI-generated summary An author testing local AI setups reports that replacing Ollama with a llama.cpp instance running on an Intel Arc A750 GPU improved performance. The source notes that using the Vulkan framework with specific flags helped achieve token generation rates around thirty-three to thirty-five tokens per second for Gemma 4 E4B.