cloudninjas.ca

Monday 16 November

Uber’s Legal AI Agent Cuts Contract Review Time by 20% with Rules and RAG
AI-generated summary Uber reports that its Legal Redlining Agent has reduced average contract review time by more than 20% while achieving 91% accuracy in its decisions. Integrated into Microsoft Word, the agent uses retrieval-augmented generation, historical lawyer feedback, and deterministic rules to analyze proposed contract changes and recommend policy-aligned responses.

Also covered bynews.lavx.huCloudNinjas
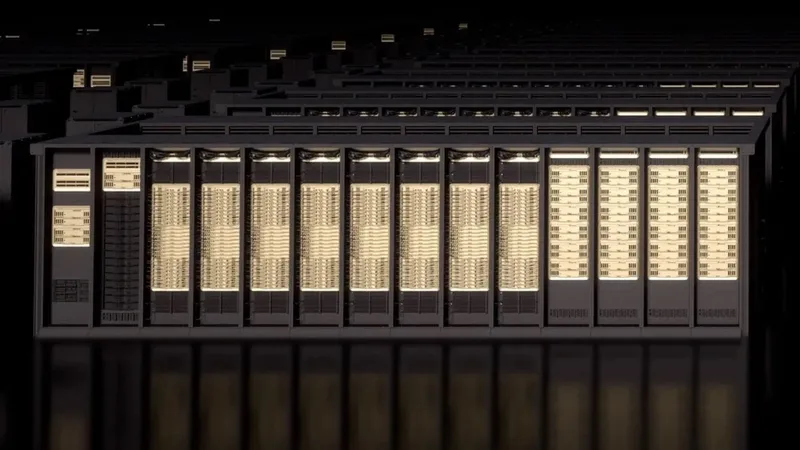
Lambda Boosts AI Factory Resiliency and Efficiency With NVIDIA Photonics

AI-generated summary Lambda is utilizing NVIDIA Photonics co-packaged optics switches to connect NVIDIA GB300 NVL72 racks featuring more than 10,000 GPUs. Lambda says the deployment delivers lower power usage, higher resiliency, and longer mean time between interruptions to its AI factory infrastructure.

Also covered bysdxcentral.comData PhoenixCloudNinjas
Earlier:

NVIDIA Vera Rubin NVL72 Achieves up to 2x Blackwell Ultra Performance in MLPerf Training v6.1

AI-generated summary NVIDIA says its Vera Rubin NVL72 platform achieved up to 2x more performance than a Blackwell Ultra baseline in MLPerf Training v6.1. NVIDIA says the new architecture delivered the fastest time to train on six of the seven benchmarks in its inaugural run.

Also covered byNVIDIA Blogdevotd.CloudNinjas
Earlier:

NVIDIA Platforms Gain Traction in Korean Physical AI and Agentic Workloads

AI-generated summary NVIDIA platforms gained traction among Korean enterprises and startups deploying robotics, edge artificial intelligence, and agentic workflows at AI Day Seoul. Over two thousand attendees participated in the event to explore hardware and software stacks including Isaac, DGX, and OpenShell.

Also covered byTokenTimesaiunderstanding.orgTechPowerUp
Earlier:

Sunday 15 November

Saturday 14 November

Local AWS Emulator reshapes the verification loop for coding agents

AI-generated summary AWS released a locally runnable emulator built entirely by autonomous coding agents that reproduces the behavior of more than 200 AWS services. The change allows existing AWS SDK calls to target emulated endpoints without code changes by setting a single environment variable on a developer machine.

Earlier:

Sparse Autoencoders Enable Direct Tool Choice Auditing in LLM Agents via Kiji Inspector

AI-generated summary Dataiku presents Kiji Inspector, an open-source tool that applies Sparse Autoencoders to decision tokens to audit large language model agent tool selections. Engineers can inspect sparse activation patterns and layer activation values pulled from a patched vLLM engine to identify dominant influences on agent choices.

Earlier:

Integrating Google’s Gemini Decision API: Faster, Lower‑Cost Bounded Choices for AI Workloads

AI-generated summary Google released the Gemini Decisions API featuring the Gemini Decision 1 model to evaluate predefined options in a single pass without generating text. Google reports that the new model delivers sub-250 ms latency and token-only pricing while already using it internally for detecting potentially adversarial behavior in Search.

Also covered bybyteiota | From Bits to Bytes
Earlier:

Claude Fable 5.2 reduces safeguard blocks, speeds up multi‑turn coding, and lowers token pricing

AI-generated summary Anthropic introduces Claude Fable 5.2 with a reported 55 percent drop in overall safeguard blocks and up to a 60 percent reduction in cybersecurity-related prompts compared with the previous version. The new model features token pricing reduced by 20 percent and token generation speeds running up to 30 percent faster than Claude Fable 5.1.

Also covered bybyteiota | From Bits to Bytes
Earlier:

Claude Fable 5.2 vs. GPT-6 Astra: A lower list price didn’t mean a lower bill

AI-generated summary Anthropic launched Claude Fable 5.2 on Nov. 9 with standard API rates of $8 per million uncached input tokens and $40 per million output tokens. OpenAI launched GPT-6 Astra in September with standard API rates of $10 per million uncached input tokens and $50 per million output tokens.

Also covered byCloudNinjasBytechap
Earlier: