wpnews.pro · Sat 14 Nov

Saturday 14 November

llama.cpp patch speeds up one RTX 5090 matrix multiply 4.5x
AI-generated summary A newly merged patch for llama.cpp introduces Vulkan cooperative-matrix tiles that improve matrix multiplication performance. Jeff Bolz reports that narrow tiles reduced execution time for a specific matrix multiply on an RTX 5090 from 325.49 to 72.36 microseconds.
Earlier:

Gemini API CLI Official Guide (Part 1): Giving Your AI Agent a Stateless Multimodal CLI Toolbox

AI-generated summary Google individual developer CLI entry points transitioned to Antigravity CLI for specific personal and consumer account scopes. The gemini-api ships as a standalone Go binary and acts as a stateless multimodal CLI toolbox for developers.

Earlier:

Most AI Video Demos Hide the Hard Part: Keeping the Workflow Together

AI-generated summary Web Pulse reports that most artificial intelligence video demonstrations conceal the complexity of maintaining a cohesive production workflow across multiple applications. The source explains that connecting an assistant to a complete video tool through the Model Context Protocol helps manage production stages without switching interfaces.

Codex CLI Setup: 12 Steps in 60 Min [2026]

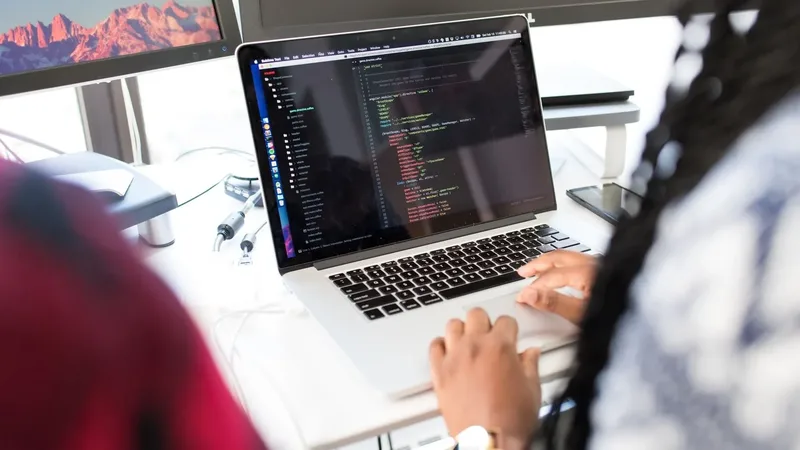
Illustrative: Two people at a desk with a laptop showing code in a text editor

AI-generated summary OpenAI reports that Codex CLI is an open-source terminal agent that edits files and runs tests in working directories. OpenAI states that users can sign in using a ChatGPT account or an API key to access models like GPT-6.1 Sol.

Also covered byWeb Pulse
Earlier:

Show HN: LetThemBuild – Claude Code, Codex, Gemini and OpenRouter in Parallel

AI-generated summary LetThemBuild is a desktop application that integrates Claude Code, Codex, Gemini, and OpenRouter to run development tasks in parallel using a lead model and reviewers. The software operates within a git worktree on macOS, Windows, or Linux and allows users to monitor and steer tasks from the Mac, web, or iPhone.

Also covered bybyteiota | From Bits to Bytes

llama.cpp reaches v1.0 with stable APIs for local AI development

AI-generated summary Hugging Face announced the release of llama.cpp version 1.0.0, which introduces stable application programming interfaces for local large language model development. The update expands distribution channels to include major package managers across Linux, macOS, Windows, and mobile platforms while enforcing strict semantic versioning rules.

Also covered byAI CompassMy blogWeb Pulse
Earlier: