dataphoenix.info · Sat 14 Nov

Saturday 14 November

Kiro Crew launches persistent bots for recurring dev work

Conceptual illustration of parallel development workstreams passing permission checkpoints into a central persistent context, with a schedule icon and a hand adjusting a control dial.

AI-generated summary Kiro launched persistent bots in Kiro Crew to handle recurring development responsibilities across multiple sessions. Kiro states that users define each bot's goals, schedules, permissions, and tool access while retaining memory control.

Earlier:

Adobe previews 10 creative experiments at MAX 2026

Conceptual illustration of a framed mountain landscape extending through translucent image planes, with a colored contour stroke and an abstract audio waveform.

AI-generated summary Adobe previewed 10 research projects spanning video, audio, imaging and design at MAX 2026. Adobe presented the innovations as research projects without release dates, pricing or commitments to Creative Cloud.

Earlier:

AssemblyAI Uses AWS Spot Instances for Cost-Effective Speech-to-Text Inference

AI-generated summary AssemblyAI uses a mixed fleet of Amazon EC2 Spot Instances and On-Demand Instances across multiple NVIDIA GPU instance families for speech-to-text inference. According to production deployment results, AssemblyAI achieved 70 percent cost savings on inference compute by using Amazon EC2 Spot Instances with GPUs.

Also covered byData Phoenix

Nebuly raises $21M to measure enterprise AI returns

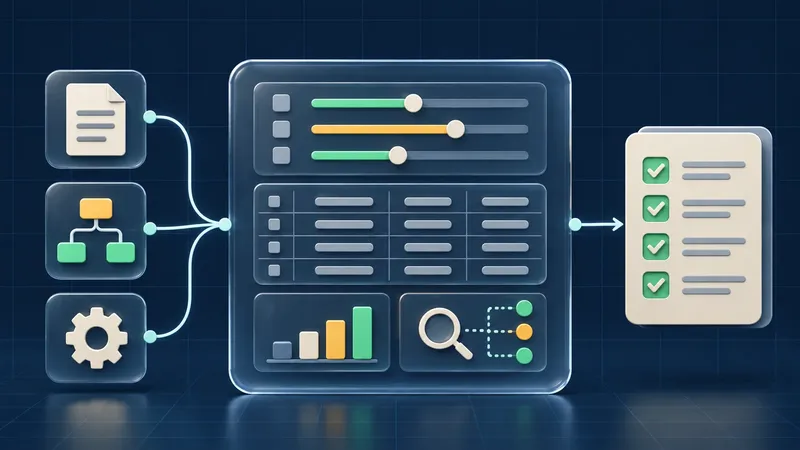
Conceptual illustration of generic enterprise AI workflow inputs flowing through an auditable measurement dashboard with adjustable controls, a data table and a results checklist.

AI-generated summary Nebuly raised $21 million in a Series A financing round led by Planven to expand its platform for measuring enterprise AI business value. The company states that the platform connects to custom agents built on Claude, ChatGPT and Microsoft Copilot while running on premises or in private clouds.

Earlier:

Octen Pulse Returns Search Results in 10 Milliseconds

Octen Pulse

AI-generated summary Octen launched the open source model Octen Pulse, which the company says returns search results in 10 milliseconds so artificial intelligence models can search while thinking. Founder and CEO Kuan Zou says the company is building search like utilities to prevent developers from having to ration it as they grow.

Also covered byData Phoenix

llama.cpp and ggml set rules for breaking changes

Unbranded layered library blocks meet at a bright compatibility boundary, with dependency arrows leading to an amber release milestone.

AI-generated summary The ggml project released the llama.cpp and ggml libraries at version 1.0.0 on November 13, committing to Semantic Versioning 2.0.0 rules for future updates. The update includes breaking cleanups that remove deprecated public application programming interfaces and legacy operations alongside various new features and backend performance work.

Earlier:

Decider v1.3 and Decider Flash v1.3 from Perplexity score 70 and 64, respectively, on the Artificial Analysis Decision…

AI-generated summary Perplexity has released Decider v1.3 and Decider Flash v1.3 as updates to their flagship decision models, featuring a context window of 256K tokens and text and image input capabilities. Decider v1.3 scores 70 on the Artificial Analysis Decision Index v2.1 while Decider Flash v1.3 scores 64, with both models available through Perplexity's first-party API under the Apache License 2.0.

Also covered byAI热报MarkTechPostData Phoenix
Earlier: