ashutoshai.com

Yesterday · Thu 19 Nov

Perplexity expands Orchestrator to proprietary models and previews automatic routing
AI-generated summary Perplexity has updated its Orchestrator API to include proprietary models alongside open-weight options and previewed automatic model selection. The interface unifies model access and billing behind a single key while supporting requests from OpenAI and Anthropic.

Also covered byPerplexity (@perplexity_ai)e/accAI Compass
Earlier:

Gemini's $19.99 task mode goes free in 6 countries

AI-generated summary Google made the task mode in its Gemini app free for users in the US, Japan, South Korea, Canada, Australia and India. Google states that the rollout runs on the Gemini 4 Hydrogen model and includes advanced features starting in the US.

Also covered byAI PingiPhone in Canada | Canada’s source for Apple, telecom, tech news, and dealsAI Compass
Earlier:

OpenAI launches GPT-6.2 Astra and Sol with lower API prices and some benchmark gains

AI-generated summary OpenAI releases two new language models named GPT-6.2 Astra and GPT-6.2 Sol, featuring lower API prices and benchmark gains. OpenAI says GPT-6.2 Astra is designed for demanding professional tasks, while GPT-6.2 Sol is built for everyday use.

Also covered bymodelgrep.comAzeem HassniAI Compass
Earlier:

Monday 16 November

Gemini Notebook now turns your sources into shareable interactive websites

AI-generated summary Google announced a new feature for Gemini Notebook that turns user sources into interactive websites like dashboards and study aids. Users can generate a site by typing a command in the notebook chat and then share the finished result with other people.

Also covered byFathom NewsAndroid AuthorityAI Compass
Earlier:

Perplexity Monitor API: $1 per 1,000 runs for web and page tracking

AI-generated summary Perplexity has released the Monitor API to check the web or specific pages on a schedule and send a signed webhook upon finding relevant updates. Pricing for the developer service is set at one dollar per one thousand succeeded runs for Search monitors and one dollar per one thousand fetched URLs for Page monitors.

Also covered byUnite.AIAravind Srinivas (@AravSrinivas)AI Compass
Earlier:

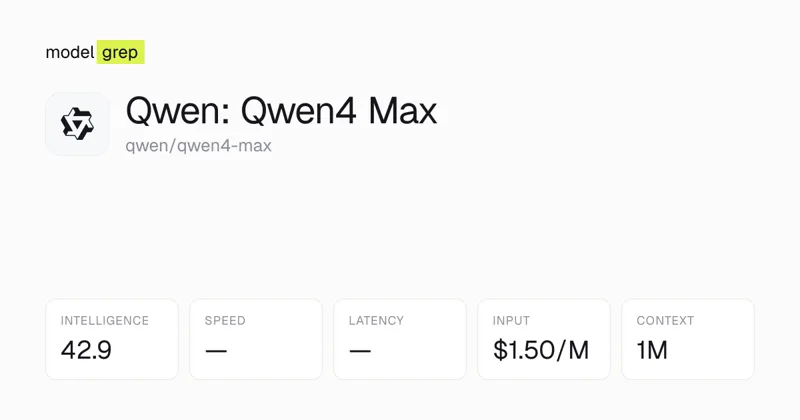
Qwen4 Max — uncensored, 42.9 intelligence, $1.50/M

Qwen: Qwen4 Max — benchmarks, speed and pricing

AI-generated summary Alibaba released the Qwen4 Max flagship model, which accepts text, image, and video inputs with a one million token context window. The model features a reasoning function enabled by default, an Artificial Analysis Intelligence Index score of 42.9, and pricing of $1.50 per million input tokens.

Also covered byAI Compassaiunderstanding.orgZeniteq
Earlier:

Tencent Launches Hy4 flash: 224B Params, 12B Active, 1M Context at 0.5 Yuan per Million Tokens

AI-generated summary Tencent released Hy4 flash on 16 November 2026 with 224 billion total parameters and a context window of 1 million tokens. Tencent prices the API at 0.5 yuan per million input tokens and states that the model is live across various platforms.

Also covered byHuggingNewsArtificialWatchAI Compass
Earlier:

Sunday 15 November

Saturday 14 November

llama.cpp reaches v1.0 with stable APIs for local AI development

AI-generated summary Hugging Face announced the release of llama.cpp version 1.0.0, which introduces stable application programming interfaces for local large language model development. The update expands distribution channels to include major package managers across Linux, macOS, Windows, and mobile platforms while enforcing strict semantic versioning rules.

Also covered byAI CompassMy blogTech AI Wire
Earlier:

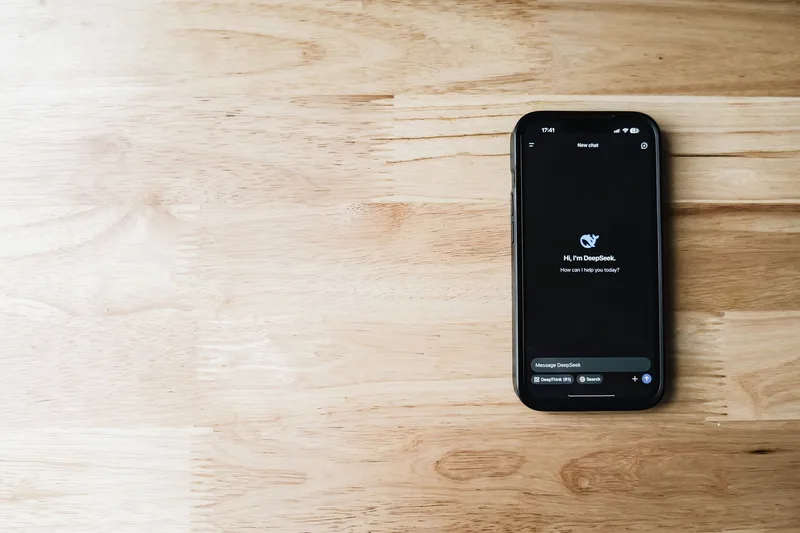
DeepSeek opens its app’s search, file and voice tools through its API

A smartphone displaying the DeepSeek app on a light wooden table.

AI-generated summary DeepSeek opened the search, file-reading, voice and safety functions behind its consumer app to developers through its API on 13 November. The deepseek-flash model serving these features is currently backed by the DeepSeek-V4.1-Flash-1017 checkpoint.

Also covered byAI Industry TodayCASRAIAI Compass
Earlier:

Friday 13 November

Congrats @thinkymachines team on Inkling 2 Small!

AI-generated summary NVIDIA AI congratulated the thinkymachines team on Inkling 2 Small. The source notes it is a 594B model pretrained in just 68 hours with NVIDIA NVFP4 on GB300 NVL72 racks.

Also covered byCASRAIAI CompassGitSeonjeap
Earlier:

Monday 9 November

ChatGPT Images 2.6, Gemini Omni 1.2 Flash and Meta’s Muse overhaul

ChatGPT Images 2.6, Gemini Omni 1.2 Flash and Meta’s Muse overhaul. AI Compass Weekly (2 to 6 Nov)

AI-generated summary OpenAI says ChatGPT Images 2.6 cut ChatGPT rendering times by 50% while adding vector SVG export, looping GIFs and markup-guided edits across two new API endpoints. Google states Gemini Omni 1.2 Flash lowered 720p video pricing by 30% to $0.07 per second alongside multi-turn 15-second shot refinements and 4K upscaling.

Earlier: