Cerebras Puts Disaggregated Inference Into Production With GPUs
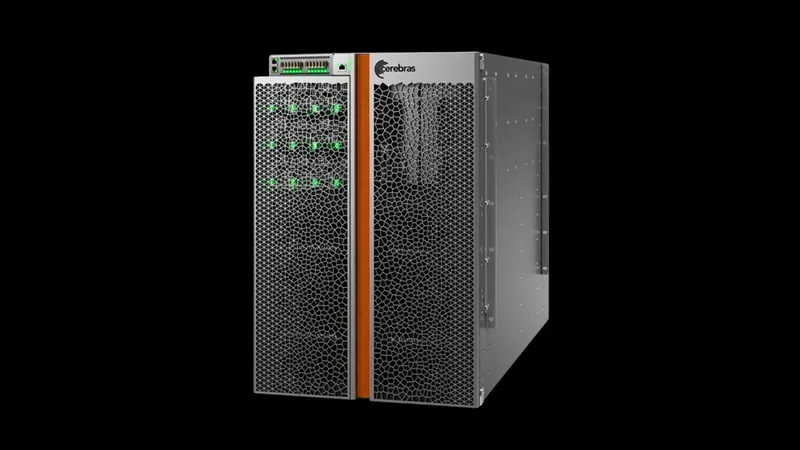
AI-generated summary Cerebras Systems reported that its production disaggregated inference deployment assigns prompt processing to AMD Instinct GPUs and response generation to CS-3 systems. The configuration delivered five times the throughput per megawatt of a CS-3-only setup without reducing token-generation speed on Cerebras Inference Cloud.
Also covered bySTIRUPnews.lavx.hu