llama-swap v273: Resource-aware selection, model routing
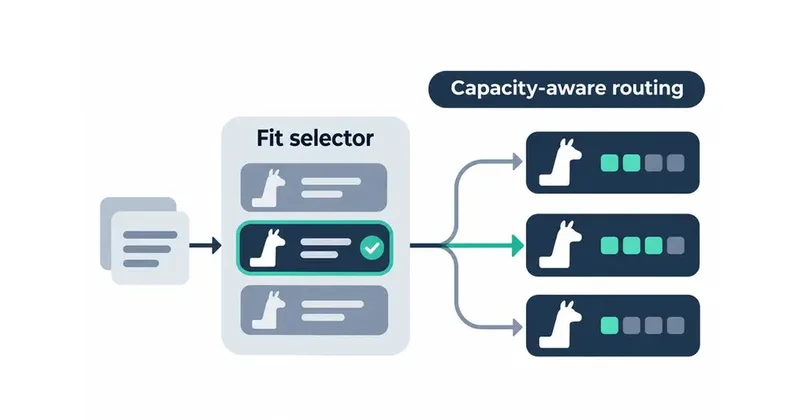
AI-generated summary The new version llama-swap v273 allows developers running AI models on one server to automatically select request targets based on remaining resources. The fit selector queries the capacity router to obtain swap plans and routes requests using evict_cost values assigned to models that would be unloaded.