devotd.net

Today · Fri 20 Nov

TokenEconomizer: Repository-specific learning, cost savings
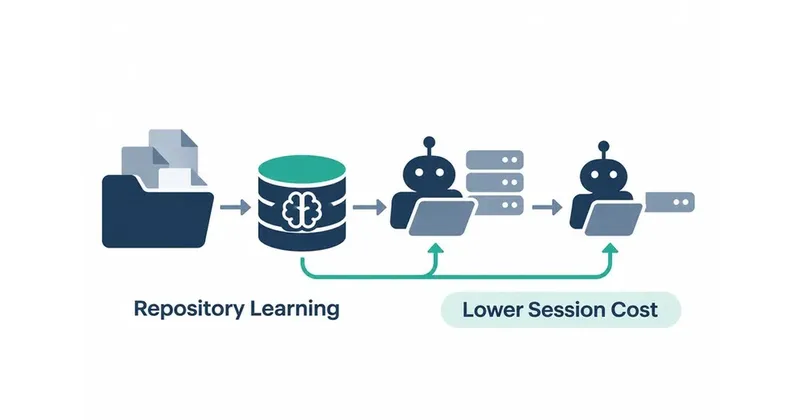
On a white background, blue-gray right arrows link a navy folder holding documents, a navy cylinder with a teal top and brain motif, and two navy robots in front of blue-gray panels. To the right of the two robots are three blue-gray bars and one blue-gray bar, respectively. A teal line from beneath the cylinder splits into upward arrows beneath the two robots. At the bottom are the labels ‘Repository Learning’ and ‘Lower Session Cost’, the latter on a pale teal rounded background.

AI-generated summary TokenEconomizer is an open-source plugin from UC Berkeley, Microsoft Research, and Microsoft Security designed to reduce the cost of AI coding agents rediscovering familiar procedures and loading unused tools. According to the company, average costs fell by 18.4 to 30.9 percent across 277 SWE-Bench tasks, 6 repositories, and 5 agent-model combinations while largely maintaining task success rates.
Earlier:

Yesterday · Thu 19 Nov

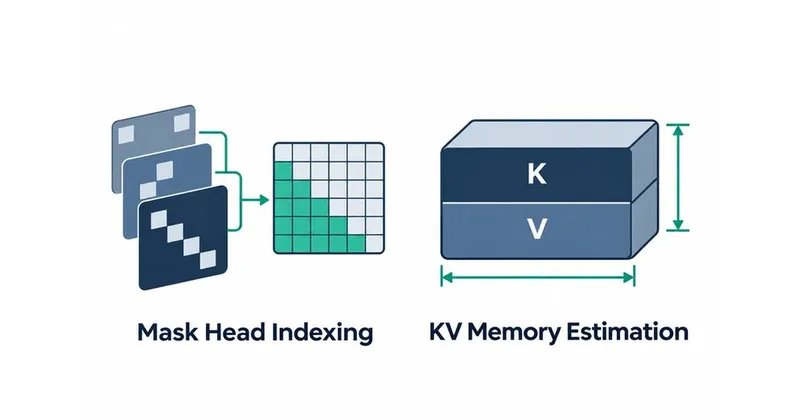
Co-Designing Sparse Attention for Efficient Long-Context Inference

AI-generated summary NVIDIA Technical Blog outlines a technical primer on co-designing sparse attention for efficient long-context inference on NVIDIA GPUs. NVIDIA Technical Blog explains how sparse attention limits token attendance and details how an indexer scores keys during prefill and decode phases.

Also covered bydevotd.explainx.aiblockchain.news

Wednesday 18 November

Monday 16 November

GitHub Launches Bulk Start for AI Scan in Public Preview (Up to 20 Repositories at Once)

DigIntoAI · AI model news, analysis and practical guides

AI-generated summary GitHub announced that bulk start for AI Scan for repositories is now available in public preview, letting security teams initiate multiple scans simultaneously. Teams can start AI Scans for up to 20 repositories at once either when enabling the organization-level setting for selected repositories or directly from the code scanning organization alerts page.

Also covered byCloudNinjasdevotd.Pondero
Earlier:

Post-Training NVIDIA Nemotron to Increase Accuracy in Your Scientific Domain

AI-generated summary NVIDIA discusses post-training its Nemotron models for scientific domains to increase accuracy. NVIDIA says supervised fine tuning improved accuracy by 12% and reinforcement learning post-training lifted it a further 17%.

Also covered byNakoda NewsData Phoenixdevotd.
Earlier:

NVIDIA Vera Rubin NVL72 Achieves up to 2x Blackwell Ultra Performance in MLPerf Training v6.1

AI-generated summary NVIDIA says its Vera Rubin NVL72 platform achieved up to 2x more performance than a Blackwell Ultra baseline in MLPerf Training v6.1. NVIDIA says the new architecture delivered the fastest time to train on six of the seven benchmarks in its inaugural run.

Also covered byNVIDIA Blogdevotd.CloudNinjas
Earlier:

New Ask Maps features to help with holiday travel and prep

AI-generated summary Google says it is launching new Ask Maps features on Android and iOS to help users build custom travel itineraries, search saved lists, and view real-time route details. Google says the new agentic capabilities allow Ask Maps to find local appointments online and call businesses for users, with availability expanding to 30 countries across Europe and more than 200 countries and territories globally.

Also covered byThe Verge9to5Googledevotd.

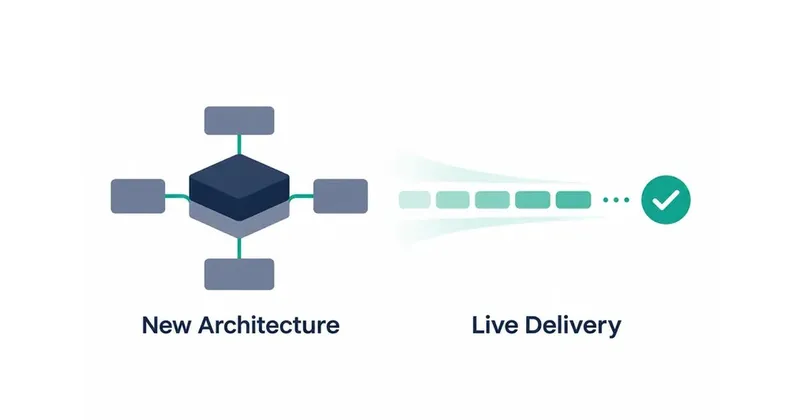
Qwen4-Max: New model architecture, phased delivery for long tasks

On a white background, layered navy and gray-blue 3D blocks on the left connect via teal lines to four gray-blue rounded rectangles above, below, left, and right. The label below reads ‘New Architecture’. On the right, five rounded rectangles in progressively darker teal sit horizontally among pale teal bands, with three small dots and a teal circle containing a white check mark. The label below reads ‘Live Delivery’.

AI-generated summary Alibaba unveiled Qwen4-Max, a model featuring a sparse mixture-of-experts architecture and a context limit of 1 million tokens. The company reports that Qwen4-Max uses phased delivery for long tasks to let developers check results early and change direction as work progresses.

Also covered byCode404ZeroTekediaSiliconANGLE

Sunday 15 November

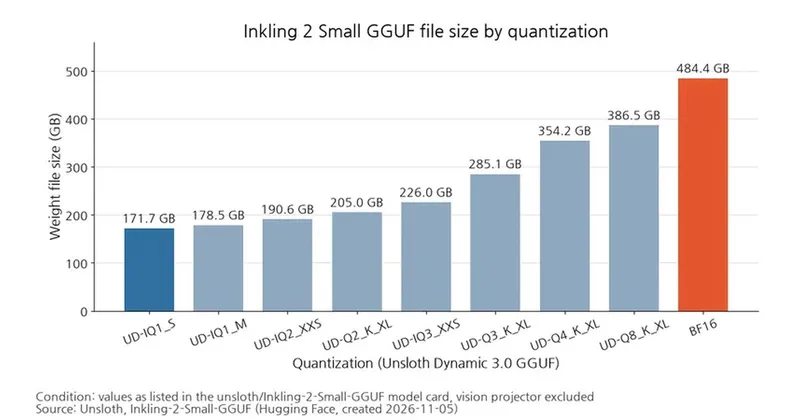
MACaQ: Lower WikiText2 perplexity than MR-GPTQ and DuQuant++ on Llama-3-8B, faster quantization and a reported 64 minutes for 122B expert layers

devotd. — Clear, source-backed reporting on IT, AI, LLMs and local AI.

AI-generated summary Huawei CSL released MACaQ to create deployable 4-bit models by processing each linear layer independently to reduce quantization time and required GPU memory. In paper experiments on Llama-3-8B using WikiText2, MACaQ achieved lower perplexity than MR-GPTQ and the DuQuant++ family.

Saturday 14 November

GitHub Copilot adds Gemini 4 Hydrogen: $1.50/$7.50 per 1M tokens, plans and credit costs

AI-generated summary GitHub made Gemini 4 Hydrogen generally available in GitHub Copilot on November 13, 2026, for subscribers on specific paid plans. GitHub scheduled the deprecation of Gemini 3.8 Flash across all Copilot experiences for December 14, 2026.

Also covered bydevotd.
Earlier:

Friday 13 November

GitHub Copilot: Selected Models Will Be Retired Starting December 14th

AI in Practice

AI-generated summary GitHub announces that several Copilot models will be retired starting December 14, 2026. The retirement requires users to update their integrations and workflows to avoid disruptions.

Also covered byDEV Communitydevotd.
Earlier: