byteiota.com · Sat 14 Nov

Saturday 14 November

AMD MEXT: AI Flash Tiering Cuts Server DRAM Costs by 83%

AI-generated summary AMD has introduced MEXT, a predictive memory software layer designed to let EPYC servers operate at half their DRAM capacity while maintaining baseline performance. AMD reports that internal deployments across 145 servers achieved an 83 percent reduction in memory expansion costs and avoided significant DRAM purchases.

Earlier:

Show HN: LetThemBuild – Claude Code, Codex, Gemini and OpenRouter in Parallel

AI-generated summary LetThemBuild is a desktop application that integrates Claude Code, Codex, Gemini, and OpenRouter to run development tasks in parallel using a lead model and reviewers. The software operates within a git worktree on macOS, Windows, or Linux and allows users to monitor and steer tasks from the Mac, web, or iPhone.

Also covered bybyteiota | From Bits to Bytes

Integrating Google’s Gemini Decision API: Faster, Lower‑Cost Bounded Choices for AI Workloads

AI-generated summary Google released the Gemini Decisions API featuring the Gemini Decision 1 model to evaluate predefined options in a single pass without generating text. Google reports that the new model delivers sub-250 ms latency and token-only pricing while already using it internally for detecting potentially adversarial behavior in Search.

Also covered bybyteiota | From Bits to Bytes
Earlier:

AI Pentesting Orchestrators: ARTEX’s Ban Created 50 New Tools

AI-generated summary Google Cloud Threat Intelligence classifies AI pentesting orchestrators as a distinct threat category following the creation of fifty new tools after the removal of ARTEX. Cloudflare reports a thirtyfold increase in daily automated requests against its customers while GitGuardian documents how agents query public repositories for secrets.

Earlier:

Claude Fable 5.2 reduces safeguard blocks, speeds up multi‑turn coding, and lowers token pricing

AI-generated summary Anthropic introduces Claude Fable 5.2 with a reported 55 percent drop in overall safeguard blocks and up to a 60 percent reduction in cybersecurity-related prompts compared with the previous version. The new model features token pricing reduced by 20 percent and token generation speeds running up to 30 percent faster than Claude Fable 5.1.

Also covered bybyteiota | From Bits to Bytes
Earlier:

Netflix’s Observability Knowledge Graph Cuts 4-Hour Incidents

AI-generated summary Netflix built an observability knowledge graph and an agentic root-cause analysis system named AutoRCA to address slow incident investigations across multiple tools. Netflix reports that large language models are used throughout the pipeline for tasks such as summarization and hypothesis generation under strict type system constraints.

Earlier:

ElevenLabs Scribe v3 Is Live: Three API Changes That Matter

AI-generated summary ElevenLabs held Summit NYC at Lincoln Center and launched Scribe v3 in the API. The company also announced 15 MW of NVIDIA Vera Rubin compute and various product updates.

Earlier:

Runway's open-source Praxis-1 turns video AI into a robot controller

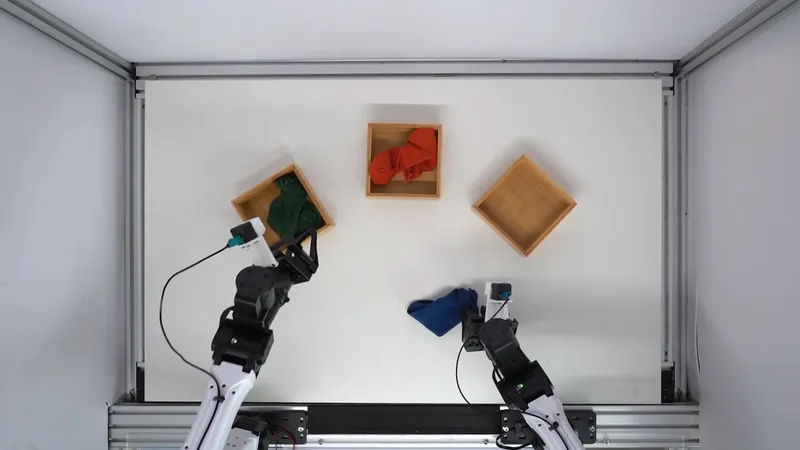
AI-generated summary AI company Runway has released its robot model Praxis-1 with open weights and source code under the Apache 2.0 license. The model uses camera images, text instructions, and position information to predict environmental changes and control robots.

Also covered byNakoda NewsSilicon AI Newsbyteiota | From Bits to Bytes
Earlier: